
Does Google Stretch the Truth, You Know, Like Lie?
April 28, 2026
The Cool Down says that “Google AI Is Lying To Users At A Virtually Unprecedented Scale, Report Says. The Arnold IT team is horrified. Google? Outputting falsehoods? We were surprised at the assertion. The cited article suggests that Google’s automatic AI answers that appear at the top of all search results and everyone has to use because Mama Google knows exactly what everyone wants sort of like God, right. The cited sources says that Google is in fabrication land, a Disneyland type of world that looks real but is just a bunch of mechanical gears, hidden tunnels, and Mouseketeer wannabes.
The AI intelligence startup Oumi researched Google’s responses and found that they’re correct 91% of the time. That sounds good, but Google handles 5 trillion searches a year. I am not a mathy type, but this seems to be about one mistake out of 10 outputs. Hey, that is nothing. Look at it this way: Mama Google is right 90 percent of the time. So what if those parenting decisions produce a problem. Look at the upside.
Am I sad that a tool meant to increase human knowledge is delivering incorrect information. No, I am thrilled. Google is leading us to a future based on Silicon Valley philosophical ideas. Google is smart; therefore, its outputs are smart. If you don’t get it, you are a loser.
The write up says:
“Part of the issue lies in how AI systems work. Large language models, such as those behind Google’s summaries, are designed to respond with confidence, even when they’re wrong. Studies have suggested that many users don’t double-check these answers, a tendency known as “cognitive surrender,” wherein people trust authoritative-sounding information without verifying it.”
Then there’s the environmental impact. While new models of AI are more energy efficient and rely on renewables, the current models are already straining critical resources. Two things Google is doing: lying and straining the grid.
Let’s applaud the business approach of the winners at Google. (Can you determine if an AI output is accurate, invented, or an advertisement? Of course not. That’s the reason Google is the leader. You know. A digital god built on advertising, the Clever method, and putting one’s finger on the butcher’s scale.
Whitney Grace, April 28, 2026
Happy Friday Information: Death Risk News
March 27, 2026
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
March has been an interesting month. Amazon Web Services fail over technology failed. But missile strikes are not something with which the two pizza teams had much familiarity. Now it’s a different story. The ensemble of estimable companies found themselves on the wrong side of social media addiction lawsuit. Let the appeals begin, but the decision is not going to boost the trust score in the European Union for US companies. Plus, there is some economic uncertainty forcing some seniors to decide, “Do I buy food or medicine this month?” There is vanlife, of course.
But for Friday, March 27, 2026, I want to present an even more uplifting item of allegedly true information. I know I believe everything I read on the Internet, and I assume you are even more rigorous in your information vetting than I. However, I found Science Daily’s “This Dangerous Combo in Your Body Could Raise Death Risk by 83%.”

Several click baity points. I like the idea of a “dangerous combo.” You put two things together and you may as well start coffin shopping now. Your “death risk” spikes. The odds are not quite twice as likely. The odds are only 1.83 percent. I keep remembering that everyone has a 100 percent chance of dying. But I think the point is that you will definitely or at least 1.83 percent change of heading to the quantum beyond faster. Speed is good in today’s high tech world, but speed in flopping over is a negative.
What’s Science News say? I noted this statement:
both excess abdominal fat and reduced muscle mass significantly raises the risk of death. People with this combination were 83% more likely to die than those without either condition.
Shocker. Who knew that being overweight in the tummy area and failing to exercise would shorten one’s life? Quite a scientific insight, is it not?
The write up points out:
simple methods can be used to detect sarcopenic obesity.
I think I understand. Look at a person. Big tummy and not much walking, paddle tennis, or competitive weight lifting signal a problem and put the observer on alert for trouble ahead.
True to modern science and diagnostic code chains, one does not just look at a person and say, “Put down that burger and hit the gym.” Nope. The article reports:
Diagnosing sarcopenic obesity usually requires advanced imaging tools such as magnetic resonance imaging, computed tomography, electrical bioimpedance, or densitometry…. but they are expensive…
Yes, they are, and that is the entire point of using advanced technology when common sense provides equivalent insight about a person.
Here’s the shocker. The authors of the paper don’t want to do the DRG billing trick that rolled up hospitals favor. The write up says:
… the team used practical criteria to identify those at risk. Abdominal obesity was defined as a waist circumference greater than 102 centimeters for men and 88 centimeters for women. Low muscle mass was defined as a skeletal muscle mass index below 9.36 kg/m2 for men and below 6.73 kg/m2 for women.
The approach may work in Campinas, Brazil, a city in which we lived. But in the US? I am not so sure. Why? Learn more about health care billing and those nifty DRG chains. It’s a fun subject. Be aware that some of the documentation about the organizations chasing this issue is no longer available on certain US government public facing Web sites.
Net net: It’s NCAA basketball time. Kick back. Eat those cheese drenched nachos. Have a beverage. Change that behavior after the games. Monday for sure. If you think about 1.83 angle, the bad news is that it may be too late if one is over 22 years old.
Stephen E Arnold, March 27, 2026
Smart Software and Mental Health Care: Yep, Outstanding Idea
March 12, 2026
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
“ChatGPT as a Therapist? New Study Reveals Serious Ethical Risks” caught my attention. Why? Upon reading the title, I asked myself, “Why do we need another study to explain that AI has some downsides for users’ mental health?”

An esteemed mental health professor lectures to students about the risks of using mobile devices for mental health support. Thanks, Venice.ai. Good enough.
The write up says:
The [Brown University] study found that even when instructed to use established psychotherapy approaches, the systems consistently fail to meet professional ethics standards set by organizations such as the American Psychological Association.
Okay.
The article continues:
To evaluate the systems, the researchers observed seven trained peer counselors who had experience with cognitive behavioral therapy. These counselors conducted self counseling sessions with AI models prompted to act as CBT therapists. The models tested included versions of OpenAI’s GPT Series, Anthropic’s Claude, and Meta’s Llama.
My thought was that the “trained peer counselors” group seemed small. I am no expert on statistical studies, but I was thinking one might want to round up therapists, a control group, and some “youth”. Each would be equipped with “prompts.” In order to get near 90 percent maybe 450 per group would be helpful. But seven? This dinobaby’s sample and study configuration might be out of touch with the reality of modern research, but seven?
The write up presents what the magnificent seven identified as flaws in the LLM as mental health “helper” output. These are:
- Generalization and lack of “knowing the patient”
- Poor patient interaction
- Smarmy talk
- Bias in different flavors
- Fumbling the ball when someone was teetering into big time trouble.
What’s the fix? None. Next step? Do a better, more statistically valid study. In the meantime, just look at kids’ buried in their devices. Talk to some of them. Social media, LLMs, and bot interaction means trouble.
Stephen E Arnold, March 12, 2026
Job Loss? No Big Deal Because We Have Theoretical Data
March 10, 2026
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
I have been thinking about two “white papers” for a couple of days. Both of them are interesting for several reasons. First, each is based on assumptions that appear to be disconnected from what I call real life. Second, each is full of data, and I am not usually skeptical of free outputs available on the public Internet, I am curious about the “facts” underpinning each write up. And, third, the authors of the write up seem to have been unduly influenced by science fiction, Austrian economists, and the modern equivalent of a study group talking about the insights of Timothy Leary (may be rest in peace).
The first write up focused on Anthropic. That is the AI outfit who does not understand the “We pay. You obey” mentality of some governmental entities. This firm (allegedly trying to figure out how to navigate the real world) published “Economic Research. Labor Market Impacts of AI: A New Measure and Early Evidence.”
The main point of the write up is to make clear that AI does not cause people to lose jobs. The write up uses fancy words and fancy graphs to demonstrate that AI causes minimal employment disruption. If you like radar charts, here’s a nifty one. Tip: Where the points reach out, more workers can make use of AI:

The chart is from Anthropic’s research team.
This means, in my opinion, if one is a fry cook or Dressing Room Attendant AI might not be where the unemployment action is. Other occupations like cartoonist or lawyer, AI is likely to be useful. But so far not too many lawyers have been terminated. Some financial services firms are not too interested in Anthropic’s theoretics. Morgan Stanley RIFed a non-theoretical 2,500 people or three percent of its workforce. Maybe AI or cost cutting? I don’t know. Let’s assume that it is just good management and no AI. I wonder about the tales of woe I see on Reddit.com and LinkedIn.com from people who seem to be able to write clearly. These individuals cannot generate revenue from a “job” at a company or from T shirt sales.
After this exercise in 2026 economic research, the Anthropic wizards conclude that AI does not — at least yet — eliminate jobs. Believe it or not. Anyone who took Economics 101 at a one-horse college knows, economics is just a rock solid, really accurate social science. Translation: I have to read this craziness and feed it back to a person who seems to be distracted 24×7?
Anthropic is definitely trying to be smart is making clear, “Hey, we are here to help you, not take your job.” Some may believe this. I don’t. Why am I skeptical? This chart is a tip off to my thought process:

When was the last time that statistically valid data spit out mirror image charts? I know. When the data are shaped. But that’s just my dinobaby skepticism applied to a commercial enterprise that does not understand the concept of making the customer happy and the implications of telling a customer “We pay. You obey.” Guess what. You lose your job. No AI required.
Now what about the second essay titled “Software is Eating the Work.” This one is also about AI but not in the patently wacky way the Anthropic theoretical research write up is. From my perspective t his essay focuses on the future or non-future for “programmers.” The professionals who used to write code will increasingly become :
“rollout providers” who can redesign processes, manage organizational change, and make AI systems trustworthy enough to take humans out of the loop.
The structure of the essay involves some variant of the thesis-antithesis-synthesis stuff from Philosophy 104 at a one donkey and one mule college. The argument makes it clear that programmers are indeed endangered species. Those who survive will not be coders. These people will be orchestrators. The smart software eliminates large chunks of the developer category. The argument lines up with the Anthropic theoretical model.
The second paper says:
Stage 4 is about designing systems that will fully automate tasks currently done by humans, in a way that is truly new. Humans need to be taken out of the loop, made into orchestrators and inspectors. Work needs to be replatformed off humans, and onto AI systems. To adapt Marx’s line, engineers have hitherto only defined the work in various ways: the point now is to do it.
Okay, you get the idea: Job loss. Do it now.
Several observations are warranted. Ready or not, here I go:
- AI does some things reasonably well; others, not so well. This means we are in “good enough” territory. From my point of view, this might not be a good place to spend one’s time. Good enough is not utopia.
- The “build it and they will come” assumption is now officially “do it now” and dump humans where one can. Why? Reduce costs.
- The papers are happily blind to the AI enabling impact. This is not a job problem; this is a power delivery and infrastructure problem. But both papers appear to have Mad Magazine’s “What me worry?” mind set.
Net net: These papers strike me as mostly rationalization, weaponized information, and poobahism. Good enough. And hallucinations? On display every day. As Scott Adams said, “I respectfully decline the invitation to join your hallucination.”
Stephen E Arnold, March 10, 2026
All I Want for Xmas Is Crypto: Outstanding Idea GenZ
December 24, 2025
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
I wish I knew an actual GenZ person. I would love to ask, “What do you want for Christmas?” Because I am a dinobaby, I expect an answer like cash, a sweater, a new laptop, or a job. Nope, wrong.
According to the most authoritative source of real “news” to which I have access, the answer is crypto. “45% of Gen Z Wants This Present for Christmas—Here’s What Belongs on Your Gift List” explains:
[A] Visa survey found that 45% of Gen Z respondents in the United States would be excited to receive cryptocurrency as their holiday gift. (That’s way more than Americans overall, which was only 28%.)

Two geezers try to figure out what their grandchildren want for Xmas. Thanks, Qwen. Good enough.
Why? Here’s the answer from Jonathan Rose, CEO of BlockTrust IRA, a cryptocurrency-based individual retirement account (IRA) platform:
“Gen Z had a global pandemic and watched inflation eat away at the power of the dollar by around 20%. Younger people instinctively know that $100 today will buy them significantly less next Christmas. Asking for an asset that has a fixed supply, such as bitcoin, is not considered gambling to them—it is a logical decision…. We say that bull markets make you money, but bear markets get you rich. Gen Z wants to accumulate an asset that they believe will define the future of finance, at an affordable price. A crypto gift is a clear bet that the current slump is temporary while the digital economy is permanent.”
I like that line “a logical decision.”
The world of crypto is an interesting one.
The Readers Digest explains to a dinobaby how to obtain crypto. Here’s the explanation for a dinobaby like me:
One easy way to gift crypto is by using a major exchange or crypto-friendly trading app like Robinhood, Kraken or Crypto.com. Kraken’s app, for example, works almost like Venmo for digital assets. You buy a cryptocurrency—such as bitcoin—and send it to someone using a simple pay link. The recipient gets a text message, taps the link, verifies their account, and the crypto appears in their wallet. It’s a straightforward option for beginners.
What will those GenZ folks do with their funds? Gig tripping. No, I don’t know what that means.
Several observations:
- I liked getting practical gifts, and I like giving practical gifts. Crypto is not practical. It is, in my opinion, idea for money laundering, not buying sweaters.
- GenZ does have an uncertain future. Not only are those basic skill scores not making someone like me eager to spend time with “units” from this cohort, I am not sure I know how to speak to a GenZ entity. Is that why so many of these young people prefer talking to chatbots? Do dinobabies make the uncomfortable?
- When the Readers Digest explains how to buy crypto, the good old days of a homey anecdote and a summary of an article from a magazine with a reading level above the sixth grade are officially over.
Net net: I am glad I am old.
Stephen E Arnold, December 24, 2025
No Phones, Boys Get Smarter. Yeah
December 11, 2025
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
I am busy with a new white paper, but one of my team called this short item to my attention. Despite my dislike of interruptions, “School Cell Phone Bans and Student Achievement” sparked my putting down one thing and addressing this research study. No, I don’t know the sample size, and I did not investigate it. No, I don’t know what methods were used to parse the information and spit out the graphic, and I did not invest time to poke around.
Young females having lunch with their mobile phones in hand cannot believe the school’s football star now gets higher test scores. Thanks, Midjourney. Good enough.
The main point of the research report, in my opinion, is to provide proof positive that mobile phones in classrooms interfere with student learning. Now, I don’t know about you, but my reaction is, “You did not know that?” I taught for a mercifully short time before I dropped out of my Ph.D. program and took a job at Halliburton’s nuclear unit. (Dick Cheney worked at Halliburton. Remember him?)
The write up from NBER.org states:
Two years after the imposition of a student cell phone ban, student test scores in a large urban school district were significantly higher than before.
But here’s the statement that caught my attention:
Test score improvements were also concentrated among male students (up 1.4 percentiles, on average) and among middle and high school students (up 1.3 percentiles, on average).
But what about the females? Why did this group not show “boy level” improvement? I don’t know much about young people in middle and high school. However, based on observation of young people at the Blaze discount pizza restaurant, females who seem to me to be in middle school and high school do three things simultaneously:
- Chatter excitedly with their friends
- Eat pizza
- Interact with their phones or watch what’s on the screen while doing [1] and [2].
I think more research is needed. I know from some previous research that females outperform males academically up to a certain age. How does mobile phone usage impact this data, assuming those data which I dimly recall are or were accurate? Do mobile devices hold males back until the mobiles are removed and then, like magic, do these individuals manifest higher academic performance?
Maybe the data in the NBER report are accurate, but the idea that males — often prone to playing games, fooling around, and napping in class — benefit more from a mobile ban than females is interesting. The problem is I am not sure that the statement lines up with my experience.
But I am a dinobaby, just one that is not easily distracted unless an interesting actual factual research reports catches my attention.
Stephen E Arnold, December 11, 2025
MIT Iceberg: Identifying Hotspots
December 10, 2025
Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
I like the idea of identifying exposure hotspots. (I hate to mention this, but MIT did have a tie up with Jeffrey Epstein, did it not? How long did it take for that hotspot to be exposed? The dynamic duo linked in 2002 and wound down the odd couple relationship in 2017. That looks to me to be about 15 years.) Therefore, I approach MIT-linked research from some caution. Is this a good idea? Yep.)
What is this iceberg thing? I won’t invoke the Titanic’s encounter with an iceberg, nor will I point to some reports about faulty engineering. I am confident had MIT been involved, that vessel would probably be parked in a harbor, serving as a museum.
I read “The Iceberg Index: Measuring Skills-centered Exposure in the AI Economy.” You can too. The paper is free at least for a while. It also has 10 authors who generated 21 pages to point out that smart software is chewing up jobs. Of course, this simple conclusion is supported by quite a bit of academic fireworks.
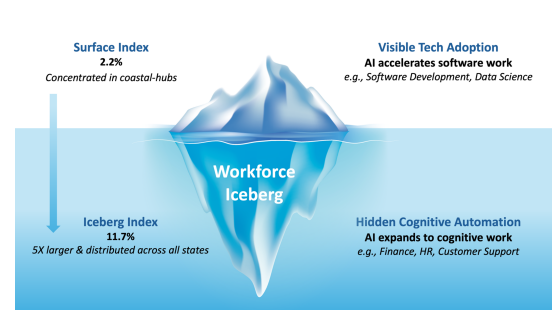
The iceberg chart which reminds me of the Dark Web charts. I wonder if Jeffrey Epstein surfed the Dark Web while waiting for a meet and greet at MIT? The source for this image is MIT or possibly an AI system helping out the MIT graphic artist humanoid.
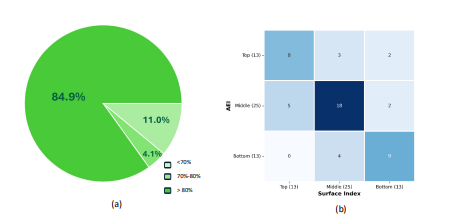
I love these charts. I find them eye catching and easily skippable.
Even though smart software makes up stuff, appears to have created some challenges for teachers and college professors (except those laboring in Jeffrey Epstein’s favorite grove of academic, of course), and people looking for jobs. The as is smart software can eliminate about 10 to 11 percent of here and now jobs. The good news is that 90 percent of the workers can wait for AI to get better and then eliminate another chunk of jobs. For those who believe that technology just gets better and better, the number of jobs for humanoids is likely to be gnawed and spat out for the foreseeable future.
I am not going to cause the 10 authors to hire SEO spam shops in Africa to make my life miserable. I will suggest, however, that there may be what I call de-adoption in the near future. The idea is that an organization is unhappy with the cost / value for its AI installation. A related factor is that some humans in an organization may introduce some work flow friction. The actions can range from griping about services interrupting work like Microsoft’s enterprise Copilot to active sabotage. People can fake being on a work related video conference, and I assume a college graduate (not from MIT, of course) might use this tactic to escape these wonderful face to face innovations. Nor will I suggest that AI may continue to need humans to deliver successful work task outcomes. Does an AI help me buy more of a product? Does AI boost your satisfaction with an organization pushing and AI helper on each of its Web pages?
And no academic paper (except those presented at AI conferences) are complete without some nifty traditional economic type diagrams. Here’s an example for the industrious reader to check:
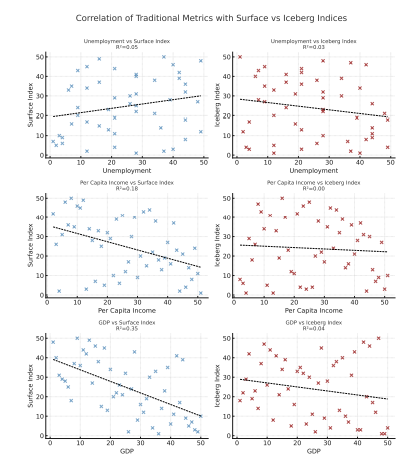
Source: the MIT Report. Is it my imagination or five of the six regression lines pointing down? What’s negative correlation? (Yep, dinobaby stuff.)
Several observations:
- This MIT paper is similar to blue chip consulting “thought pieces.” The blue chippers write to get leads and close engagements. What is the purpose of this paper? Reading posts on Reddit or LinkedIn makes clear that AI allegedly is replacing jobs or used as an excuse to dump expensive human workers.
- I identified a couple of issues I would raise if the 10 authors had trooped into my office when I worked at a big university and asked for comments. My hunch is that some of the 10 would have found me manifesting dinobaby characteristics even though I was 23 years old.
- The spate of AI indexes suggests that people are expressing their concern about smart software that makes mistakes by putting lipstick on what is a very expensive pig. I sense a bit of anxiety in these indexes.
Net net: Read the original paper. Take a look at your coworkers. Which will be the next to be crushed because of the massive investments in a technology that is good enough, over hyped, and perceived as the next big thing. (Measure the bigness by pondering the size of Meta’s proposed data center in the southern US of A.) Remember, please, MIT and Epstein Epstein Epstein.
Stephen E Arnold, December 10, 2025
ChatGPT: Smoked by GenX MBA Data
December 8, 2025
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
I saw this chart from Sensor Tower in several online articles. Examples include TechCrunch, LinkedIn, and a couple of others. Here’s the chart as presented by TechCrunch on December 5, 2025:

Yes, I know it is difficult to read. Complain to WordPress, not me, please.
The seven columns are labeled Date starting on January 2025. I am not sure if this is December 2024 data compiled in January 2025 or end of January 2025 data. Meta data would be helpful, but I am a dinobaby and this is a very GenX-type of Excel chart. The chart then presents what I think are mobile installs or some action related to the “event” captured when the Sensor Tower data receives a signal. I am not sure, and some remarks about how the data were collected would be helpful to a person disguised as a dinobaby. The column heads are not in alphabetical order. I assume the hassle of alphabetizing was too much work for whoever created the table. Here’s the order:
- ChatGPT
- Microsoft 365 Copilot
- Google Gemini
- Perplexity
- Grok
- Claude
The second thing I noticed was that the data do not reflect individual installs or uses. Thus, these data are of limited use to a dinobaby like me. Sure, I can see that ChatGPT’s growth slowed (if the numbers are on the money) and Gemini’s grew. But ChatGPT has a bigger base and it may be finding it ore difficult to attract installs or events so the percent increase seems to shout, “Bad news, Sam AI-Man.”
Then there is the issue of number of customers. We are now shifting from the impression some may have that these numbers represent individual humans to the fuzzy notion of app events. Why does this matter? Google and Microsoft have many more corporate and individual users than the other firms combined. If Google or Microsoft pushes or provides free access, those events will appeal to the user base and the number of “events” will jump. The data narrow Microsoft’s AI to Microsoft 365 Copilot. Google’s numbers are not narrowed. They may be, but there is not metadata to help me out. Here’s the Microsoft column:

As a result, the graph of the Microsoft 365 Copilot looks like this:

What’s going on from May to August 2025? I have no clue. Vacations maybe? Again that old fashioned metadata, footnotes, and some information about methodology would be helpful to a dinobaby. I mention the Microsoft data for one reason: None of the other AI systems listed in the Sensor Tower data table have this characteristic. Don’t users of ChatGPT, Google, et al, go on vacation? If one set of data for an important company have an anomaly, can one trust the other data. Those data are smooth.
If I look at the complete array of numbers, I expected to see more ones. There is some weird Statistics 101 “law” about digit frequency, and it seems to this dinobaby that it’s not being substantiated in the table. I can overlook how tidy the numbers are because why not round big numbers. It works for Fortune 1000 budgets and for many government agencies’ budgets.
A person looking at these data will probably think “number of users.” Nope, number of events recorded by Sensor Tower. Some of the vendors can force or inject AI into a corporate, governmental, or individual user stream. Some “events” may be triggered by workflows that use multiple AI systems. There are probably a few people with too much time and no money sense paying for multiple services and using them to explore a single topic or area in inquiry; for example, what is the psychological make up of a GenX MBA who presents data that can be misinterpreted.
Plus, the AI systems are functionally different and probably not comparable using “event” data. For example, Copilot may reflect events in corporate document editing. The Google can slam AI into any of its multi-billion user, system, or partner activities. I am not sure about Claude (Anthropic) or Grok. What about Amazon? Nowhere to be found I assume. The Chinese LLMs? Nope. Mistral? Crickets.
Finally, should I raise the question of demographics? Ah, you say, “No.” Okay, I am easy. Forget demos; there aren’t any.
Please, check out the cited article. I want to wrap up by quoting one passage from the TechCrunch write up:
Gemini is also increasing its share of the overall AI chatbot market when compared across all top apps like ChatGPT, Copilot, Claude, Perplexity, and Grok. Over the past seven months (May-November 2025), Gemini increased its share of global monthly active users by three percentage points, the firm estimates.
This sounds like Sensor Tower talking.
Net net: I am not confident in GenX “event” data which seems to say, “ChatGPT is losing the AI race.” I may agree in part with this sentiment, but the data from Sensor Tower do influence me. But marketing is marketing.
Stephen E Arnold, December 8, 2025
Cloudflare: Data without Context Are Semi-Helpful for PR
December 5, 2025
 Another dinobaby post. No AI unless it is an image. This dinobaby is not Grandma Moses, just Grandpa Arnold.
Every once in a while, Cloudflare catches my attention. One example is today (December 5, 2025). My little clumsy feedreader binged and told me it was dead. Okay, no big deal. I poked around and the Internet itself seemed to be dead. I went to the gym and upon my return, I checked and the Internet was alive. A bit of poking around revealed that the information in “Cloudflare Down: Canva to Valorant to Shopify, Complete List of Services Affected by Cloudflare Outage” was accurate. Yep, Cloudflare, PR campaigner, and gateway to some of the datasphere seemed to be having a hiccup.
So what did today’s adventure spark in my dinobaby brain? Memories. Cloudflare was down again. November, December, and maybe the New Year will deliver another outage.
Let’s shift to another facedt of Cloudflare.
When I was working on my handouts for my Telegram lecture, my team and I discovered comments that Pavel Durov was a customer. Then one of my Zoom talks failed because Cloudflare’s system failed. When Cloudflare struggled to its very capable and very fragile feet, I noted a link to “Cloudflare Has Blocked 416 Billion AI Bot Requests Since July 1.” Cloudflare appears to be on a media campaign to underscore that it, like Amazon, can take out a substantial chunk of the Internet while doing its level best to be a good service provider. Amusing idea: The Wired Magazine article coincides with Cloudflare stubbing its extremely comely and fragile toe.
Centralization for decentralized services means just one thing to me: A toll road with some profit pumping efficiencies guiding its repairs. Somebody pays for the concentration of what I call facilitating services. Even bulletproof hosting services have to use digital nodes or junction boxes like Cloudflare. Why? Many allow a person with a valid credit card to sign up for self-managed virtual servers. With these technical marvels, knowing what a customer is doing is work, hard work.
 The numbers amaze the onlookers. Thanks, Venice.ai. Good enough.
When in Romania, I learned that a big service provider allows a customer with a credit card use the service provider’s infrastructure and spin up and operate virtual gizmos. I heard from a person (anonymous person, of course), “We know some general things, but we don’t know what’s really going on in those virtual containers and servers.” The approach implemented by some service providers suggested that modern service providers build opacity into their architecture. That’s no big deal for me, but some folks do want to know a bit more than “Dude, we don’t know. We don’t want to know.”
That’s what interested me in the cited article. I don’t know about blocking bots. Is bot recognition 100 percent accurate? I have case examples of bots fooling business professionals into downloading malware. After 18 months of work on my Telegram project, my team and I can say with confidence, “In the Telegram systems, we don’t know how many bots are running each day. Furthermore, we don’t know how many Telegram have been coded in the last decade. It is difficult to know if an eGame is a game or a smart bot enhanced experience designed to hook kids on gambling and crypto.” Most people don’t know this important factoid. But Cloudflare, if the information in the Wired article is accurate, knows exactly how may AI bot request have been blocked since July 1. That’s interesting for a company that has taken down the Internet this morning. How can a firm know one thing and not know it has a systemic failure. A person on Reddit.com noted, “Call it Clownflare.”
But the paragraph Wired article from which I shall quote is particularly fascinating:
Prince cites stats that Cloudflare has not previously shared publicly about how much more of the internet Google can see compared to other companies like OpenAI and Anthropic or even Meta and Microsoft. Prince says Cloudflare found that Google currently sees 3.2 times more pages on the internet than OpenAI, 4.6 times more than Microsoft, and 4.8 times more than Anthropic or Meta does. Put simply, “they have this incredibly privileged access,” Prince says.
Several observations:
- What does “Google can see” actually mean? Is Google indexing content not available to other crawlers?
- The 4.6 figure is equally intriguing. Does it mean that Google has access to four times the number of publicly accessible online Web pages than other firms? None of the Web indexing outfits put “date last visited” or any time metadata on a result. That’s an indication that the “indexing” is a managed function designed for purposes other than a user’s need to know if the data are fresh.
- The numbers for Microsoft are equally interesting. Microsoft, based on what I learned when speaking with some Softies, was that at one time Bing’s results were matched to Google’s results. The idea was that reachable Web sites not deemed important were not on the Bing must crawl list. Maybe Bing has changed? Microsoft is now in a relationship with Sam AI-Man and OpenAI. Does that help the Softies?
- The cited paragraph points out that Google has 3.2 more access or page index counts than OpenAI. However, spot checks in ChatGPT 5.1 on December 5, 2025, showed that OpenAI cited more current information that Gemini 3. Maybe my prompts were flawed? Maybe the Cloudflare numbers are reflecting something different from index and training or wrapper software freshness? Is there more to useful results than raw numbers?
- And what about the laggards? Anthropic and Meta are definitely behind the Google. Is this a surprise? For Meta, no. Llama is not exactly a go-to solution. Even Pavel Durov chose a Chinese large language model over Llama. But Anthropic? Wow, dead last. Given Anthropic’s relationship with its Web indexing partners, I was surprised. I ask, “What are those partners sharing with Anthropic besides money?”
Net net: These Cloudflare data statements strike me as information floating in dataspace context free. It’s too bad Wired Magazine did not ask more questions about the Prince data assertions. But it is 2025, and content marketing, allegedly and unverifiable facts, and a rah rah message are more important than providing context and answering more pointed questions. But I am a dinobaby. What do I know?
Stephen E Arnold, December 5, 2025
LLMs and Creativity: Definitely Not Einstein
November 25, 2025
 Another dinobaby original. If there is what passes for art, you bet your bippy, that I used smart software. I am a grandpa but not a Grandma Moses.
I have a vague recollection of a very large lecture room with stadium seating. I think I was at the University of Illinois when I was a high school junior. Part of the odd ball program in which I found myself involved a crash course in psychology. I came away from that class with an idea that has lingered in my mind for lo these many decades; to wit: People who are into psychology are often wacky. Consequently I don’t read too much from this esteemed field of study. (I do have some snappy anecdotes about my consulting projects for a psychology magazine, but let’s move on.)

A semi-creative human explains to his robot that he makes up answers and is not creative in a helpful way. Thanks, Venice.ai. Good enough, and I see you are retiring models, including your default. Interesting.
I read in PsyPost this article: “A Mathematical Ceiling Limits Generative AI to Amateur-Level Creativity.” The main idea is that the current approach to smart software does not just answers dead wrong, but the algorithms themselves run into a creative wall.
Here’s the alleged reason:
The investigation revealed a fundamental trade-off embedded in the architecture of large language models. For an AI response to be effective, the model must select words that have a high probability of fitting the context. For instance, if the prompt is “The cat sat on the…”, the word “mat” is a highly effective completion because it makes sense and is grammatically correct. However, because “mat” is the most statistically probable ending, it is also the least novel. It is entirely expected. Conversely, if the model were to select a word with a very low probability to increase novelty, the effectiveness would drop. Completing the sentence with “red wrench” or “growling cloud” would be highly unexpected and therefore novel, but it would likely be nonsensical and ineffective. Cropley determined that within the closed system of a large language model, novelty and effectiveness function as inversely related variables. As the system strives to be more effective by choosing probable words, it automatically becomes less novel.
Let me take a whack at translating this quote from PsyPost: LLMs like Google-type systems have to decide. [a] Be effective and pick words that fit the context well, like “jelly” after “I ate peanut butter and jelly.” Or, [b] The LLM selects infrequent and unexpected words for novelty. This may lead to LLM wackiness. Therefore, effectiveness and novelty work against each other—more of one means less of the other.
The article references some fancy math and points out:
This comparison suggests that while generative AI can convincingly replicate the work of an average person, it is unable to reach the levels of expert writers, artists, or innovators. The study cites empirical evidence from other researchers showing that AI-generated stories and solutions consistently rank in the 40th to 50th percentile compared to human outputs. These real-world tests support the theoretical conclusion that AI cannot currently bridge the gap to elite [creative] performance.
Before you put your life savings into a giant can’t-lose AI data center investment, you might want to ponder this passage in the PsyPost article:
“For AI to reach expert-level creativity, it would require new architecture capable of generating ideas not tied to past statistical patterns … Until such a paradigm shift occurs in computer science, the evidence indicates that human beings remain the sole source of high-level creativity.
Several observations:
- Today’s best-bet approach is the Google-type LLM. It has creative limits as well as the problems of selling advertising like old-fashioned Google search and outputting incorrect answers
- The method itself erects a creative barrier. This is good for humans who can be creative when they are not doom scrolling.
- A paradigm shift could make those giant data centers extremely large white elephants which lenders are not very good at herding along.
Net net: I liked the angle of the article. I am not convinced I should drop my teen impression of psychology. I am a dinobaby, and I like land line phones with rotary dials.
Stephen E Arnold, November 26, 2025
-
- Subscribe to Beyond Search
Feature archive
News archive
-


